Cloud Genomics Pipeline for a Mid-Size Research Institute
Let's Connect
Overview
What we built
A genomics research institute was producing sequencing data faster than its scientists could analyse it, with a six-week backlog and no two projects processing samples the same way. We replaced hand-run scripts with an automated cloud pipeline.
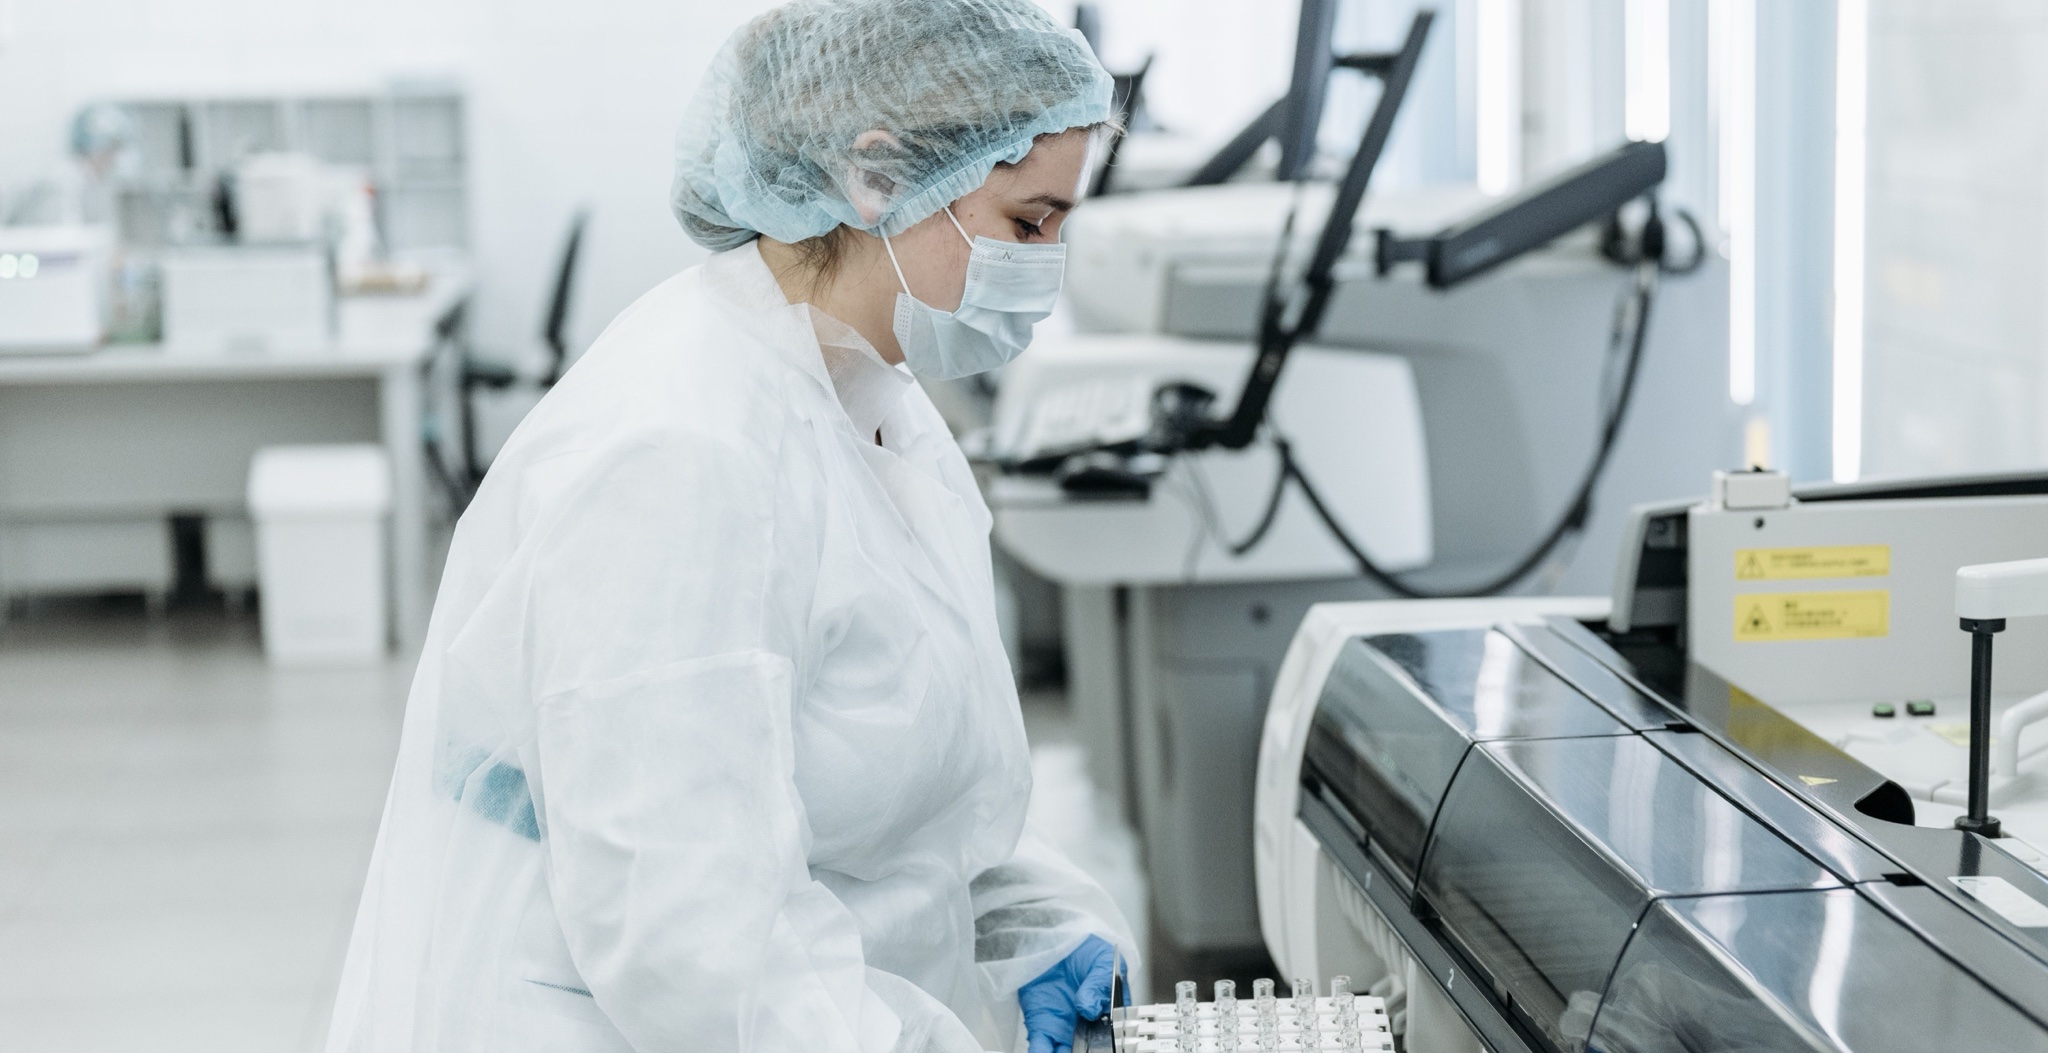
In plain terms: the institute's sequencing machines were doing their job, and the analysis behind them could not keep up. Every completed run waited for a scientist to process it with hand-maintained scripts on a single on-premise server, a queue that had stretched to six weeks. Because each project handled samples slightly differently, results were hard to reproduce or compare, and researchers hired to do science were spending their time shepherding computations instead.
We built a cloud pipeline that takes over the moment a sequencing run finishes. It picks the run up automatically, processes it through one standardised, containerised workflow, checks the quality of the output, and files versioned results with a full record of how they were produced. Per-sample processing fell from roughly 5 days to 11 hours, the 6-week backlog cleared within the first month, compute cost per run dropped 38%, and failed or manually reprocessed runs fell from 17% to under 4%.
The Problem
Data outpacing analysis
Sequencing throughput had grown into a genuine strength for the institute, and analysis had quietly become the bottleneck behind it. Every run landed on a single on-premise server, where scientists processed samples with hand-maintained scripts that only their authors fully understood. When the server was busy, everything queued. By the time we were engaged, the backlog stood at six weeks and was still growing.
The deeper problem was consistency. No two projects processed samples quite the same way: scripts drifted apart as individual researchers tweaked parameters, and there was no shared record of which version produced which result. That made findings difficult to reproduce internally and awkward to compare across projects, exactly the properties genomics research depends on to hold its conclusions together.
The people cost was just as real. Scientists were spending research hours shepherding jobs, restarting failures and reprocessing runs by hand instead of interpreting results. Analysis capacity was capped by one machine and a handful of script owners, while the sequencers upstream kept producing more data every week with nothing downstream able to scale to meet them.
One overloaded server
Every run competed for the same on-premise machine, so processing queued behind whatever was already running and the backlog compounded week after week.
Hand-maintained scripts
Analysis lived in scripts individual scientists maintained themselves, with parameters drifting between projects and no shared, versioned definition of the standard workflow.
Irreproducible results
With no two projects processing samples the same way, results were difficult to reproduce or compare, undermining confidence in any cross-project analysis.
Manual failure handling
Failed runs were spotted late and reprocessed by hand, consuming scientist time that should have gone into interpreting the data itself.
What it was costing them
The six-week backlog meant every downstream decision waited on analysis that had already been paid for. Scientists lost research time to job shepherding and manual reprocessing, a meaningful share of runs failed or had to be redone, and the single server put a hard ceiling on how much sequencing the institute could usefully commission, regardless of how much its machines could produce.
The Solution
Automated cloud sequencing pipeline
We designed the pipeline around one principle: a completed sequencing run should need no human hands to become analysed, quality-checked, versioned output. The platform watches for finished runs, picks each one up automatically and executes a standardised workflow covering alignment, variant calling and quality control, with every step running in containers so the same code behaves the same way on every run.
Provenance is built in rather than bolted on. Every output is versioned and written to object storage together with a full record of the workflow, parameters and container versions that produced it, so any result can be traced and rerun exactly. Automated quality-control gates catch problem runs at the point of failure instead of days later, when the trail has gone cold.
Compute stopped being a fixed asset. Each run scales up the capacity it needs in the cloud, executes, and shuts itself down, with autoscaling spot instances keeping the cost per run low. Scientists follow every sample through a dashboard rather than asking whoever owns the server, and the institute's analysis capacity now grows with its sequencing output.
Key decisions
Standardise one workflow
Alignment, variant calling and quality control were consolidated into a single containerised workflow, replacing per-project scripts with one shared, versioned definition every run follows.
Automate the pickup
The pipeline detects each completed sequencing run and starts processing on its own, removing the queue of runs waiting for a scientist to launch scripts.
Version everything with provenance
Every output lands in object storage with the exact workflow version and parameters that produced it, so results can be reproduced and compared with confidence.
Gate on automated QC
Quality checks run inside the pipeline and stop bad runs early, turning failure handling from manual detective work into a flagged, explainable event.
Scale compute per run
Cloud compute spins up for each run and shuts down afterwards, with autoscaling spot instances replacing a permanently overloaded on-premise server.
Measurable Impact
What changed after launch
The pipeline changed the institute's tempo. Per-sample processing time fell from roughly 5 days to 11 hours, and the 6-week analysis backlog cleared within the first month of operation. Automated QC gates cut failed or manually reprocessed runs from 17% to under 4%, and autoscaling spot instances brought compute cost per run down by 38%.
The quieter win is reproducibility. Every project now runs the same versioned workflow, every result carries its full provenance, and scientists track samples through a dashboard instead of chasing a shared server. Analysis capacity scales with sequencing output, so growth in the lab no longer means growth in the queue.
Processing time
Roughly 5 days per sample on a shared server
11 hours per sample, fully automated
Analysis backlog
A 6-week queue, still growing
Cleared within the first month of operation
Run failures
17% of runs failed or needed manual reprocessing
Under 4% with automated QC gates
Compute cost
A fixed on-premise server, always on
Autoscaling spot instances, cost per run down 38%
Headline results
Per-sample processing time reduced from roughly 5 days to 11 hours
A 6-week analysis backlog cleared within the first month of operation
Compute cost per run cut by 38% using autoscaling spot instances
Failed or manually reprocessed runs dropped from 17% to under 4% with automated QC gates
Tech & Tools Used
What powered the build
Every tool below earned its place in this engagement. Here is the part each one played.

Nextflow
Defines the standardised sequencing workflow, chaining alignment, variant calling and quality control into one versioned pipeline that every run follows.
AWS Batch
Runs the pipeline's compute in the cloud, scaling capacity up for each run on spot instances and shutting it down again when the work is done.
AWS S3
Object storage for versioned pipeline outputs, holding every result alongside the provenance record that describes exactly how it was produced.

Docker
Packages each workflow step as a container, so alignment and variant calling behave identically on every run regardless of where the compute happens.

Python
Powers the automation glue, from detecting completed sequencing runs to registering samples and finished outputs in the tracking database.
BWA & GATK toolchain
The core bioinformatics engines inside the workflow, performing read alignment and variant calling on every sample the pipeline processes.

Terraform
Describes the whole cloud environment as code, so the infrastructure behind the pipeline is reproducible, reviewable and safe to evolve.

PostgreSQL
Tracks every sample, run and output as it moves through the pipeline, providing the state behind the scientists' dashboard.

Grafana
Monitors pipeline health and run progress, surfacing failures and queue behaviour to the team operating the platform day to day.

React
The scientist-facing dashboard, showing where each sample sits in the pipeline and linking through to its finished, versioned outputs.
Ready to Build your Life Sciences & Research Business with Data Engineering for AI
Ask Byte
Ask Byte
Typically replies instantly
just Now
Hi! I'm OrganByte's assistant. How can I help you today?
AI-generated content may be incorrect